A video studio that runs in your browser.
Write a short script, cast one of 30 actors, ask the chat for a sharper hook, then render an MP4 with a real voice. Open source, with no account, and your projects stay on your device.
In your browser
- The whole studio, its database and your renders live in this tab.
- Kokoro voices and captions, rendered in the tab: on your GPU when the browser has WebGPU, on the CPU otherwise.
- A script chat that runs on your GPU too: no key, no server.
Chrome or Edge. The voices download once, on your first render: 326 MB with WebGPU, 92 MB on the CPU.
On your server
- Cloud video models with your own keys: Veo, Kling, Seedance.
- Your own GPU through ComfyUI, or the local renderer.
- Keys stay on your server, encrypted at rest.
One docker compose up. Cloud providers bill your own account.
From a script to an MP4
The project in the video, step by step. Each step is a page of the studio, the same in both editions; the times jump the video to it.
-
Start a project
Pick a platform, a format and a language. The model picker only offers what each model can do, and says why before you launch. Then cast an actor.
-
Write the script
A line per sentence, each with an emotion that sets the delivery. Every save is a version you can restore.
- Mornings are hard.hook · neutral
- Our cold brew is smooth, strong and ready in your fridge.body · neutral
- Grab a bottle on your way out.cta · neutral
-
Ask the chat
Ask for a change in your own words. The answer is a whole new version, shown line by line against the current one, and nothing changes until you apply it. In the browser a small model answers on your GPU; a self-hosted studio uses Ollama or Claude.
Make the first line punchier. Keep the other lines.
-
Mornings are hard. But not for us!
Mornings are hard.hook ·
neutralexcited -
Our cold brew is smooth, strong and ready in your fridge.
body · neutral
-
Grab a bottle on your way out.
cta · neutral
Longer than the 9 s clip. Ask for a shorter version, or relaunch on a longer clip.
The proposal as the video shows it: a new hook, delivered excited, and the other lines kept as asked. It runs past the 9 s clip, so Apply & relaunch renders it on a longer one, and the new take lasts 11.3 s. You read every proposal before you apply it.
-
-
Render it
In the browser edition, Kokoro voices each line and the frames are drawn and encoded in the tab. A self-hosted studio sends the same project to a cloud model, ComfyUI or the local renderer, and follows its progress.
-
Watch it, then download it
The render plays on the project page with its voice. Every render is a draft until you export it; the MP4 is named after the project, the model and the time.
- cold-brew-launch-kokoro-voice-captions-2026-10-06-2006.mp4
- 720×1280 · H.264 + AAC · 11.3 s
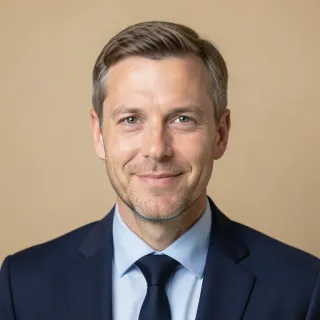
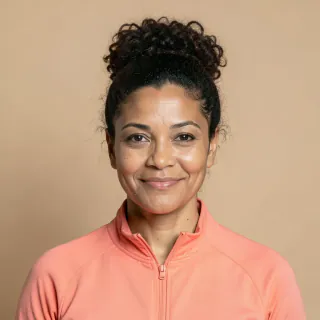
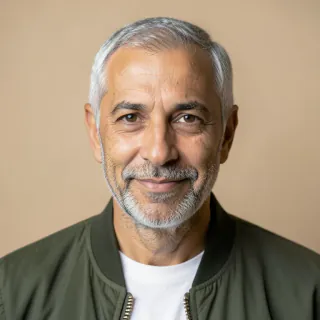
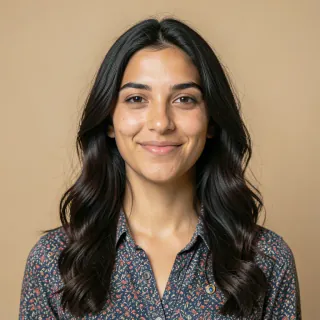
Thirty actors, six pictures each
Synthetic people, generated for Troupe with FLUX.2 [klein]: nobody was photographed. Each has a voice and six pictures: a front view, two profiles and three expressions. A render’s actor card shows the front picture, or the happy, calm or excited one on lines with that emotion; the AI video mode draws no card. With a cloud video model the actor guides the prompt, and the face changes from one render to the next.
 Léa
 Marcus
 Aiko
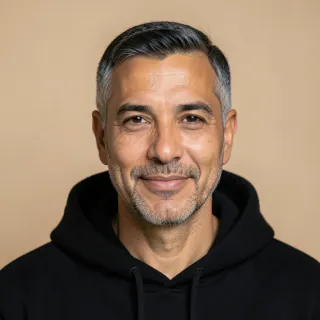 Diego
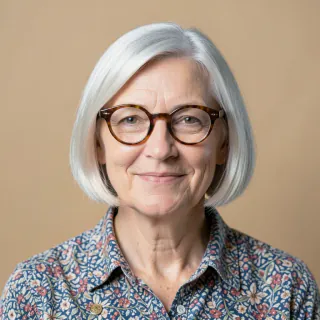 Nora
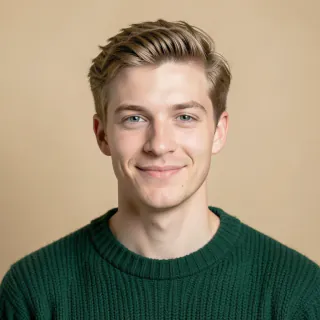 Ethan
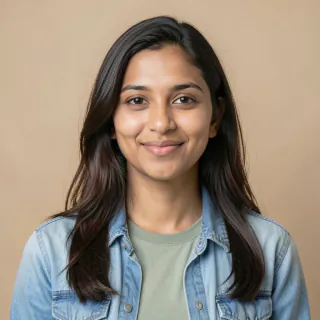 Priya
 Jonas
 Zoé
 Malik
 Ines
 Viktor
 Sam
 Chloé
 Andre
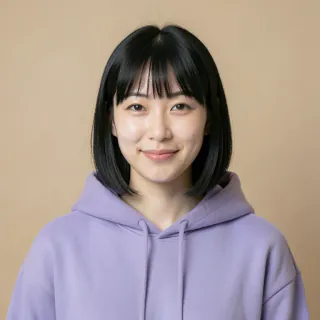 Yuki
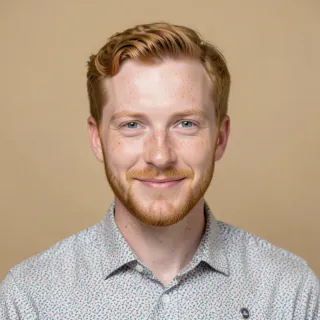 Owen
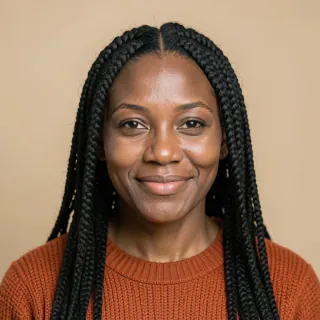 Fatou
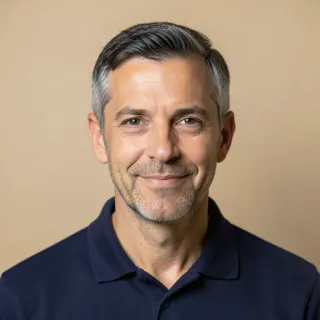 Luca
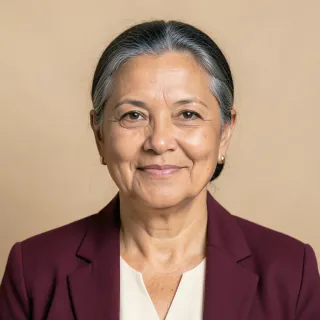 Maya
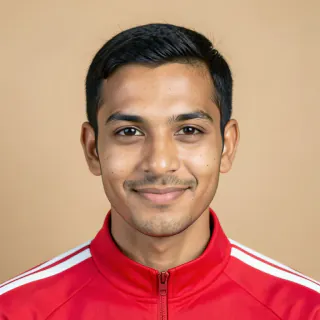 Ravi
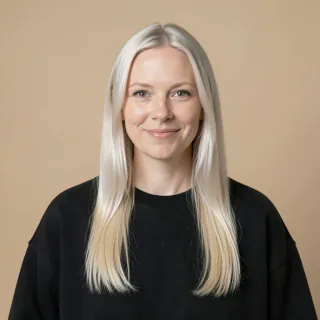 Elsa
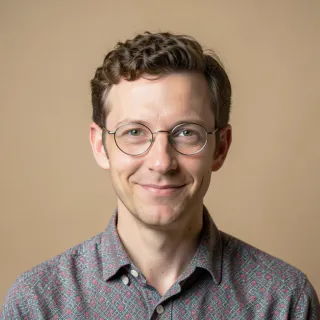 Tom
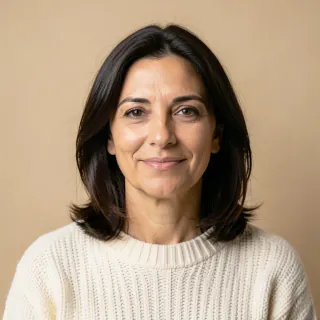 Nadia
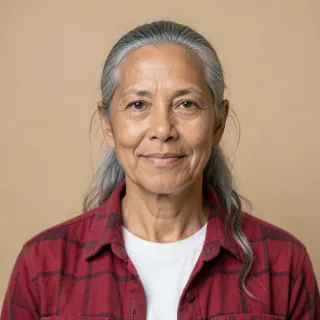 Kai
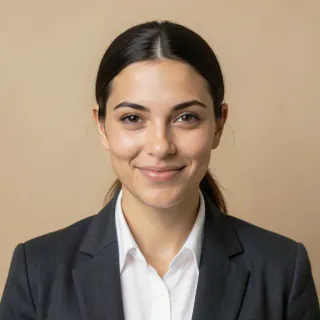 Sofia
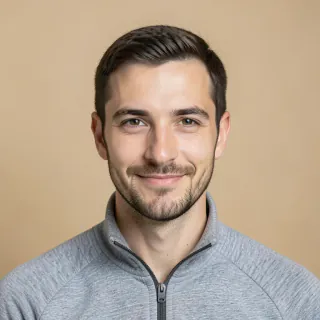 Hugo
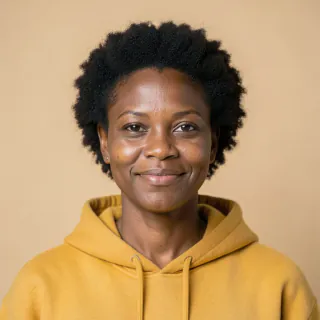 Amara
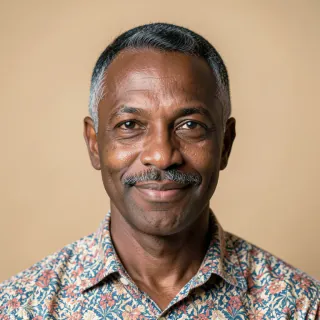 Louis
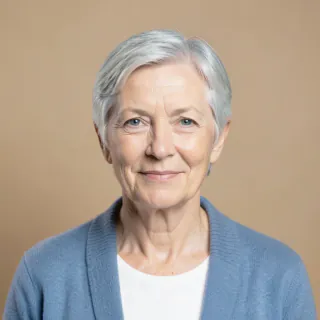 Emma
Two editions, the same studio
The same pages and the same router. What one edition cannot do is marked where it would be, with the reason.
| In your browser | On your server | |
|---|---|---|
| Where it runs | This tab: Postgres compiled to WebAssembly, kept in the browser’s storage. | Docker on your machine or a server, with PostgreSQL. Vercel and Supabase work too. |
| Your data | On this device only. Export a backup to move it; clearing the site’s data deletes it. | Docker volumes on the server: the database, the videos and the key that encrypts saved API keys. |
| Video models | Kokoro voice + captions, rendered in the tab. | Veo, Kling and Seedance with your keys; LTX-2 and Wan through ComfyUI; the local renderer, with an opt-in AI video mode; any HTTP model server. |
| Cloud models | Not here: an API key needs a server to keep it. | Billed by the provider to your own account. |
| Script chat | Qwen2.5 1.5B through WebLLM, on your GPU (880 MB, once). | Ollama, running in the Docker stack, or Claude with an Anthropic key. |
| Model servers on your machine | Not here: a page from the web cannot reach them. | ComfyUI, the local renderer, Ollama, or your own. |
| While it renders | Keep the tab open: the render runs in it. | Close the page; the server checks on the job. |
| To start | Open Troupe in your browser | Self-host with Docker |
Self-host with Docker
One command on a machine with Docker, nothing to configure. The first start downloads the chat model and the voices (about 2.6 GB), then the studio opens with the local renderer and the chat ready. Its access code is in docker compose logs app.
git clone https://github.com/maxgfr/troupe.git && cd troupe
docker compose up -d --wait
Models, and where they run
Each model declares its formats, lengths and audio; the studio only offers those, and says what it has and has not been tried on.
-
Kokoro voice + captions
browser edition- your browser
- voice
- 9:16 · 16:9 · 1:1
- 6–30 s
Rendered end to end in Chrome: the video above.
-
Local renderer
self-hosted- your CPU
- voice
- 9:16 · 16:9 · 1:1
- as long as the script
The same Kokoro voice, actor card and captions. An 8 s 720p clip takes under 4 s on an Apple M5.
-
Local renderer, AI video mode
self-hosted, opt-in- your Mac’s GPU
- voice
- LTX-Video 2B
- 5 s clip, looped
Rendered end to end on an M5 with 16 GB, about two minutes a clip. Lips do not follow the voice. NVIDIA should work; not tried.
-
LTX-2 · Wan 2.2 TI2V 5B
self-hosted, ComfyUI- your GPU
- audio / silent
- 4–10 s · 3–5 s
Workflows validated by ComfyUI 0.38.0, not yet rendered end to end. They target 24 GB NVIDIA cards.
-
Veo 3.1 Fast · Kling 3.0 · Seedance 1.5 Pro
self-hosted, your keys- Google AI · fal.ai
- audio
- 3–15 s
Tested against recorded API responses. Not yet run with paid keys for this release.
-
Your own model
self-hosted- any HTTP server
- you say
Speak the HTTP contract and declare what it can do.
Limits, plainly
- Chrome or Edge. Rendering needs WebCodecs, OffscreenCanvas and Web Locks. Other browsers open your projects and say why they cannot render.
- Downloads, once per browser. The voices are 326 MB on WebGPU (92 MB on the CPU, several times slower). The chat model is 880 MB and needs WebGPU.
- English voices. Kokoro speaks English; other languages are read with English pronunciation.
- Your projects live in one browser. Export a backup to keep them or move them; clearing the site’s data deletes them.
- No fixed face. Actors guide the voice and the prompt. Troupe does not promise the same face from a video model, dubbing or lip sync.
- Small chat model. In the browser, a 1.5B model rewrites short scripts well and long ones less so; you read every proposal before applying it.
Open source
Troupe is MIT licensed, actors’ pictures included. Some parts it uses carry other terms:
- eSpeak NG, in the browser edition
- The render worker bundles phonemizer, which embeds eSpeak NG compiled to WebAssembly. eSpeak NG is GPL-3.0-or-later, so the built site combines MIT code with GPL code; its source is on GitHub.
- Model weights
- Kokoro-82M and Qwen2.5-1.5B-Instruct are Apache 2.0. Your browser downloads them from Hugging Face; Troupe does not distribute them.
- LTX-Video, in the opt-in AI video mode
- The weights use the LTXV Open Weights License, which is not an open-source license: free under $10M of annual revenue, and bound to use restrictions, among them saying that content is machine generated and not impersonating anyone.
- FFmpeg, in the Docker image
- GPL, run as a separate program.